Collaborative Dictionary Digitization
In 2027, SIGTYP is hosting a Shared Task on Collaborative Dictionary Digitization. According to UNESCO, around 3,000 languages could disappear before the end of the century, at a rate of one every two weeks. Dictionaries are particularly important resources for language documentation, translation, education and community-led language revitalization (Mosel, 2004; Garrett,2018). Many dictionaries are only available as hard copies in libraries or archives and are spread all over the world, often far away from the communities who initially contributed to their collection. A welcome development in recent years is that libraries and other organizations have begun sharing their scanned versions online. Still, scans cannot be searched, updated,or adjusted. Neither they can be used to create a mobile app for language learning or revitalization. Digitizing dictionaries and presenting them in a structured format opens tremendous opportunities for both communities and researchers, and in some cases can be a substantial step towards language revitalization.
Aims and Goals
AIM 1: Create a collaborative network of researchers including linguists, computer scientists, and members of speech communities to work together on dictionary digitization;
AIM 2: Perform evaluation of OCR and dictionary parsing systems in terms of their accuracy, usability, and the total cost;
AIM 3: Produce high-quality digitized dictionaries that require minimum post-editing effort to be turned into gold standard ones.
Subtasks
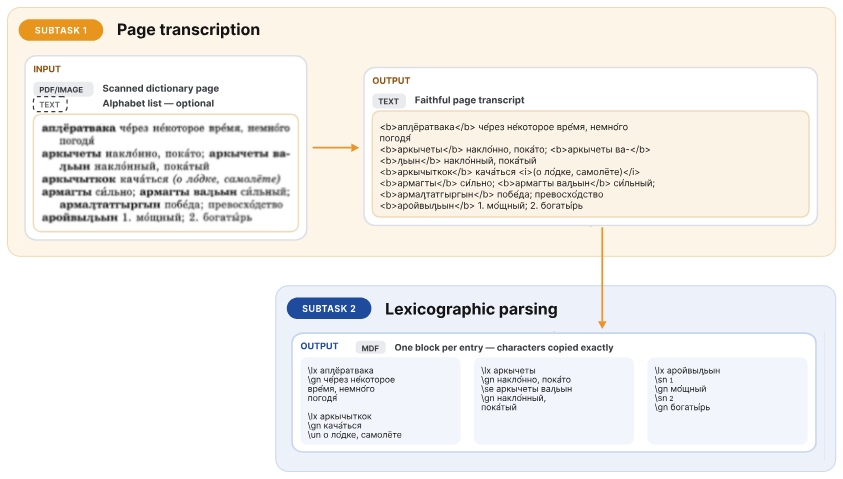
Following an established pipeline (Setiawan et al, 2026; MUDIDI), we will focus on two major subtasks:
Subtask 1: Faithful transcription (OCR)
This stage focuses on vanilla OCR: transforming an input PDF file into a plain text one, preserving the layout.
Input: a) pdf (scanned or native) of the dictionary pages which should be digitized, b) pdf (scan or native) of the introductory pages of the dictionary
Output: plain text, formatted with layout and markup
Evaluation Metrics: WER, CER, Read Order Edit, Markup F1
Baselines: Mathpix, PaddleOCR, Tesseract
Subtask 2: Dictionary Parsing
This stage focuses on dictionary parsing: transforming an input PDF or transcribed text file into a structured format.
Input: plain text file preserving layout and markup
Output: plain text file, with MDF layout
Evaluation metrics: Entry F1 (Entry Detection Accuracy), Field Assignment F1 (Assigning tags/labels), ReadOrderEdit
Baselines: a RoBERTa-based sequence labelling model
Combined Task:
This stage focuses on the overall performance of the system on the task of digitizing a dictionary.
Input: a) pdf (scanned or native) of the dictionary pages to be digitized, b) pdf (scan or native) of the introductory pages of the dictionary
Output: plain text file, with MDF layout
All systems will also be evaluated in terms of their estimated cost and token usage (for API- and subscription-based approaches), as well as reproducibility and ease of use of the code.
You may submit a system to subtask 1 alone, subtask 2 alone, or both subtasks!
Datasets and Task Setup
The task is organized in three phases: (1) Data Collection and System Development; (2) System Evaluation; (3) Full Digitization.
:: An important note about Data collection, System Development and Evaluation ::
For each dictionary we will provide a three-page sample and its introductory (usage) section, if it exists. Systems will be evaluated and ranked based on their performance on these three-page samples.
The shared task also features two roles: (1) Data Contributor; (2) System Developer (shared task participant).
Data contributors register their dictionaries for digitization, annotate the three page samples, and then vote for the best system for their dictionary. System developers design models for both or either of the tasks, provide access to the models and assist in running the models if they are selected by data contributors. Participants are welcome to register as both data contributors and system developers.
Data Collection and System Development: At the start of the data collection phase, we will invite expressions of interests from linguists and communities who would like to register their dictionaries for digitization. They will also be asked to provide a gold standard transcription of a 3-page sample of their dictionaries (the organizers can provide them with silver-standard transcripts to ease the process). These annotated samples will be used for evaluation of the systems. During the data collection phase, system developers will have access to a sample of 26 dictionaries with gold-standard annotations collected ealier as a part of the MUDIDI dataset. They can use these dictionaries to fine-tune their systems.
System Evaluation: Once the data collection phase finishes, systems will be evaluated on the new dictionary samples collected from data contributors. System developers submit their system predictions for each dictionary along with the system (e.g., via a GitHub repository). For each dictionary registered for the shared task, the organisers will then list each system's performance and provide its predictions as well as cost estimates. They will also assess each system in terms of its usability. The data contributors will then vote for the best system for their dictionaries and choose the one to use for the full dictionary digitization.
Full Digitization: During the full digitization phase, some dictionaries which are in the public domain will be fully digitized collaboratively and (optionally) shared via eLexi.org. During this phase systems will additionally be evaluated on cost, time, and issues arising in a full digitization task (e.g. hallucinations).
In addition to this, the shared task allows participants to use external resources as long as they are openly available and can be, in theory, used by other participants for research purposes. In case participants decide to use external resources and data in their system they should cite these resources and provide details of the datasets used in the system description.
Participants will be invited to describe their system in a paper for the SIGTYP workshop proceedings. The task organizers will write an overview paper that describes the task and summarizes the different approaches taken, and analyzes their results. Data contributors and shared task participants are welcome to co-author the overview paper. Data contributors are also invited to write a paper on their experience in digitizing full dictionaries.
Important Links
↣ Register as a Data Contributor!
↣ Register as a Shared Task Participant!
↣ Shared Task GitHub repository (provides the data, baseline models, and evaluation scripts)
Important Dates
Data contributors sign up: ↣ TBA
Data preparation: ↣ TBA
Training data release: ↣ TBA
System evaluation phase: ↣ TBA
Data contributors voting: ↣ TBA
System descriptions are due: ↣ TBA
Camera-ready due: ↣ TBA
Task Organizers
Doreen Osmelak, PhD Student, the University of Melbourne
David Setiawan, Research Assistant, the University of Melbourne
Charles Kemp, Professor, the University of Melbourne
Luuk Suurmeijer, Research Scientist, Royal Netherlands Academy of Arts and Sciences, Netherlands
Andreas Shcherbakov, Research Scientist
Terry Regier, Professor, University of California, Berkeley
Nick Thieberger, Assoc Professor, the University of Melbourne
Ryan Cotterell, Asst Professor, ETH Zurich
Ekaterina Vylomova, Senior Lecturer, the University of Melbourne
Contact
Please contact Ekaterina Vylomova and Doreen Osmelak if you have any questions